TL;DR
Published 2025-08-11. Claude Opus 4.1 has the highest published median (1.000) and average score (0.945) with a 100.0% success rate and the lowest average time (85,175 ms). Claude Sonnet 4 has the lowest average score among models with a 100.0% success rate (0.684).
- Published
- 2025-08-11
- Published model rows
- 14
- Evidence
- Historical task evaluation
Follow this evaluation
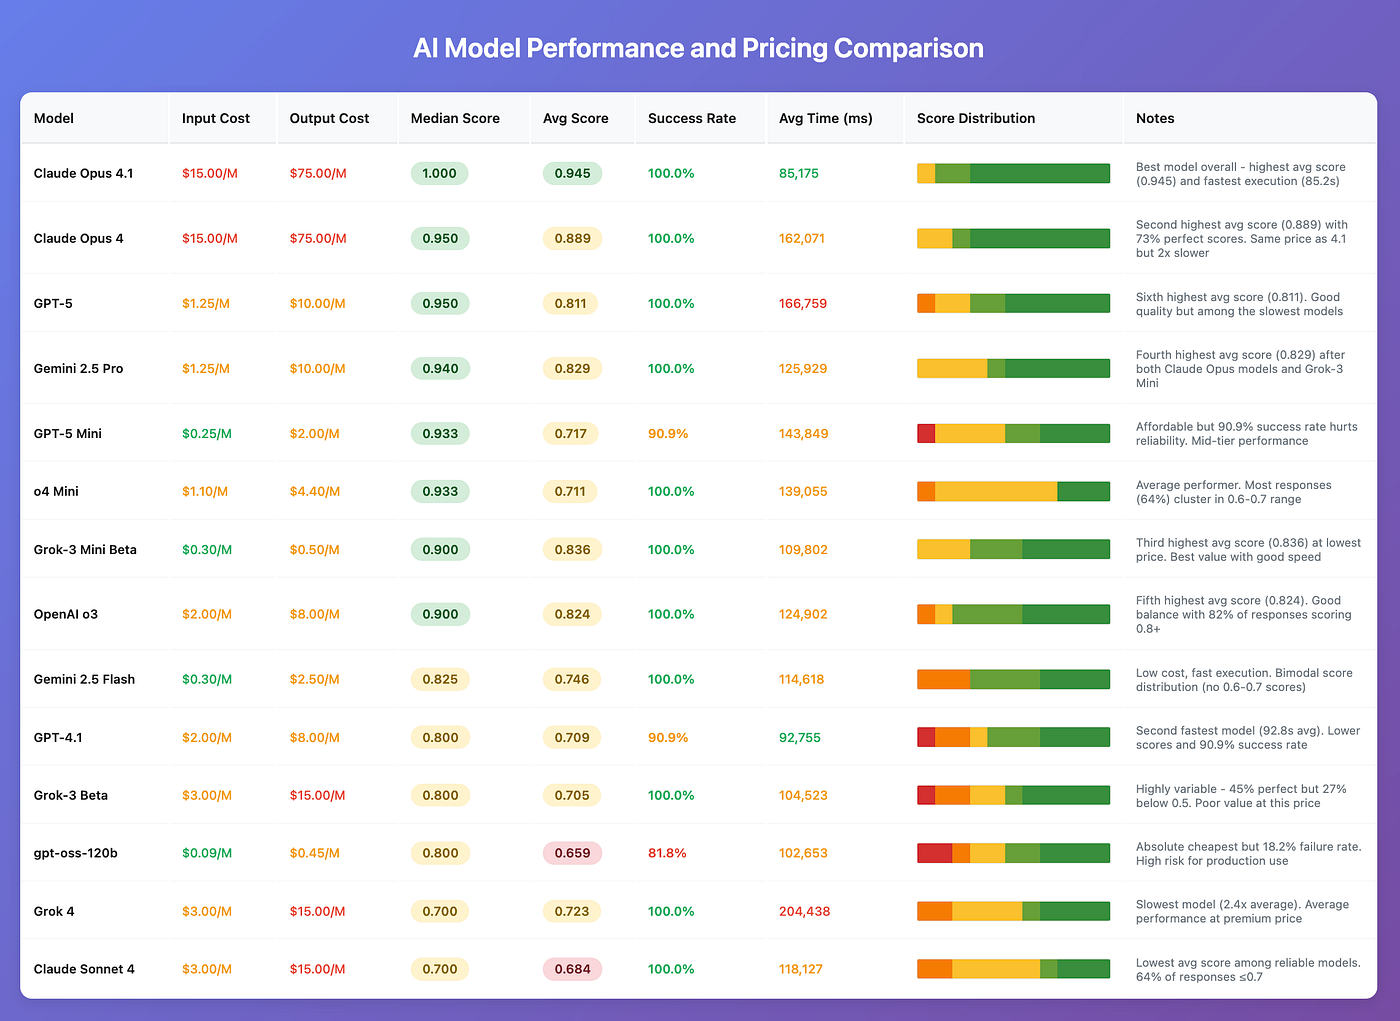
Published results
Models turning plain-English trading rules into strategy configs: source evidence dated 2025-08-11.
- Exact model version
- Claude Opus 4.1
- Median score
- 1.000
- Avg score
- 0.945
- Success rate
- 100.0%
- Avg time (ms)
- 85,175
- Input cost
- $15.00/M
- Output cost
- $75.00/M
The displayed values belong to the identified model versions and this published task, with their original metric units.
What did this task require the model to return?
Read the tested version, task and rubric together. Check failures alongside successful answers; compare costs only within the reported unit.
2025-08-11: Models turning plain-English trading rules into strategy configsKeep the study date and exact model ID beside the result. Do not average different tasks into one winner.
Test a strategy with Aurora
Keep the study date and exact model ID beside the result. Do not average different tasks into one winner.
Test a strategy with AuroraKeep reporting dates and units beside the answer, and inspect its original citations.
Published results
Showing 12 of 14 recorded values. The complete table is below.
Showing 12 of 14 recorded values. The complete table is below.
Showing 12 of 14 recorded values. The complete table is below.
14 models on one sample of strategy requests, this article does not state the count (the companion article of 2025-08-12 describes the same table as 12 financial questions). Published 2025-08-11. Values retain their original units and grading scale.
See the complete published results
Scroll sideways to compare all columns. Select a heading to sort.
| Claude Opus 4.1 | 1.000 | 0.945 | 100.0% | 85,175 | $15.00/M | $75.00/M |
| Claude Opus 4 | 0.950 | 0.889 | 100.0% | 162,071 | $15.00/M | $75.00/M |
| GPT-5 | 0.950 | 0.811 | 100.0% | 166,759 | $1.25/M | $10.00/M |
| Gemini 2.5 Pro | 0.940 | 0.829 | 100.0% | 125,929 | $1.25/M | $10.00/M |
| GPT-5 Mini | 0.933 | 0.717 | 90.9% | 143,849 | $0.25/M | $2.00/M |
| o4 Mini | 0.933 | 0.711 | 100.0% | 139,055 | $1.10/M | $4.40/M |
| Grok-3 Mini Beta | 0.900 | 0.836 | 100.0% | 109,802 | $0.30/M | $0.50/M |
| OpenAI o3 | 0.900 | 0.824 | 100.0% | 124,902 | $2.00/M | $8.00/M |
| Gemini 2.5 Flash | 0.825 | 0.746 | 100.0% | 114,618 | $0.30/M | $2.50/M |
| GPT-4.1 | 0.800 | 0.709 | 90.9% | 92,755 | $2.00/M | $8.00/M |
| Grok-3 Beta | 0.800 | 0.705 | 100.0% | 104,523 | $3.00/M | $15.00/M |
| gpt-oss-120b | 0.800 | 0.659 | 81.8% | 102,653 | $0.09/M | $0.45/M |
| Grok 4 | 0.700 | 0.723 | 100.0% | 204,438 | $3.00/M | $15.00/M |
| Claude Sonnet 4 | 0.700 | 0.684 | 100.0% | 118,127 | $3.00/M | $15.00/M |
No matching rows. Clear the filter to see all records.
14 models on one sample of strategy requests, this article does not state the count (the companion article of 2025-08-12 describes the same table as 12 financial questions). Published 2025-08-11. Values retain their original units and grading scale.
Task and tested input
Convert a natural-language trading strategy request into a NexusTrade portfolio configuration of actions and conditions.
Published prompt excerpt
You are a portfolio strategy evaluator that assesses the semantic validity of trading strategies. Your task is to analyze whether a portfolio's implementation correctly matches its intended strategy.
How the runs worked
14 models on one sample of strategy requests, this article does not state the count (the companion article of 2025-08-12 describes the same table as 12 financial questions)
NexusTrade portfolio-generation pipeline (classification, outline, strategy generation, assembly) with an LLM-judge script
Step 1
Create a sample of strategy requests the platform can generate, such as rebalancing the Magnificent 7, buying and holding a list of stocks, or a simple moving average crossover.
Step 2
Have each of the tested models generate the trading strategies.
Step 3
Score each output with Gemini 2.5 Pro and GPT-5 using the evaluator system prompt.
Step 4
Compute summary statistics and sort models by median score.
How to read the measurements
Grading and valid output
LLM judges score each configuration from 0 to 1 using published guidelines (1.0 perfect match, 0.8 to 0.9 minor issues, 0.5 to 0.7 significant discrepancies, 0.2 to 0.4 major errors, 0.0 to 0.1 complete mismatch). Success rate is reported separately.
Cost
The table lists each model's list price per million input and output tokens. It does not publish total run cost.
Time
Average time per generation in milliseconds, as published in the table.
Why this model was selected
The article selected Claude Opus 4.1 as the best model for this task and added it to the NexusTrade chat model list, while noting it costs far more per token than GPT-5 and Gemini 2.5 Pro.
See the published results
This image was published with the 2025-08-11 article. Read the source for the full test procedure and every result it reports.
Sample and scope
August 2025 snapshot with model versions that have since been replaced. The number of requests per model is not published.
Scores come from LLM judges (Gemini 2.5 Pro and GPT-5), and GPT-5 is also one of the graded models.
The score measures whether a configuration matches the requested rules, not the trading returns of the generated strategies.
No comments yet.