TL;DR
Published 2024-06-25. On the custom-indicator prompt (Test 2), Claude 3.5 Sonnet's configuration was graded 100% accurate after about 180 seconds, while GPT-4o's was misconfigured after 44 seconds. GPT-4o's final response was faster on Test 1 as well (about 53.5 seconds against 83.5 seconds).
- Published
- 2024-06-25
- Published model rows
- 2
- Evidence
- Historical task evaluation
Follow this evaluation
Published results
Claude 3.5 Sonnet and GPT-4o generating trading portfolio configs: source evidence dated 2024-06-25.
- Exact model version
- Claude 3.5 Sonnet
- Test 1 result
- —
- Test 1 final response
- ~83.5s
- Test 2 result
- 100% accurate
- Test 2 final response
- ~180s
- Input price
- $3/MTok
- Output price
- $15/MTok
The displayed values belong to the identified model versions and this published task, with their original metric units.
What did this task require the model to return?
Read the tested version, task and rubric together. Check failures alongside successful answers; compare costs only within the reported unit.
2024-06-25: Claude 3.5 Sonnet and GPT-4o generating trading portfolio configsKeep the study date and exact model ID beside the result. Do not average different tasks into one winner.
Test a strategy with Aurora
Keep the study date and exact model ID beside the result. Do not average different tasks into one winner.
Test a strategy with AuroraKeep reporting dates and units beside the answer, and inspect its original citations.
Published results
See the complete published results
Scroll sideways to compare all columns. Select a heading to sort.
| Claude 3.5 Sonnet | — | ~83.5s | 100% accurate | ~180s | $3/MTok | $15/MTok |
| GPT-4o | Correct | ~53.5s | Misconfigured | 44s | $5.00/M | $15.00/M |
No matching rows. Clear the filter to see all records.
2 portfolio-creation prompts, 2 models, single run each. Published 2024-06-25. Values retain their original units and grading scale.
Task and tested input
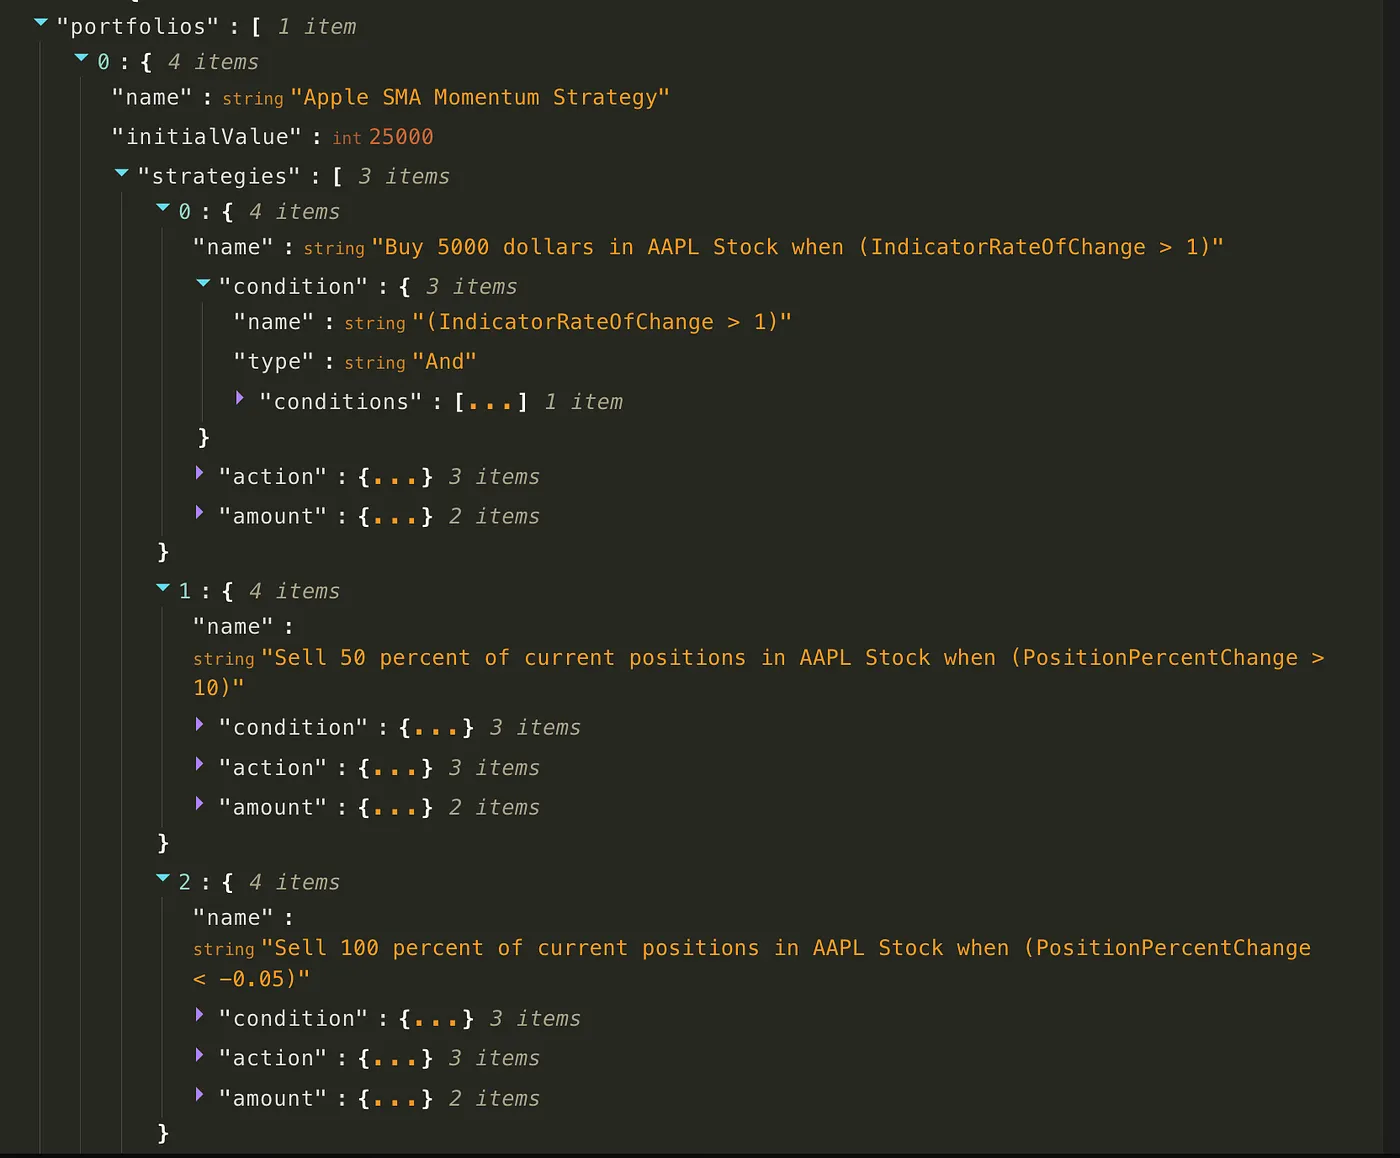
Generate a complete, syntactically valid portfolio configuration (nested strategies, conditions and indicators) from a plain-English trading request, plus a user-facing summary.
Published prompt excerpt
buy Apple when its 1 day rate of change of its 30 day Simple Moving Average is greater than 1
How the runs worked
2 portfolio-creation prompts, 2 models, single run each
NexusTrade Aurora "Create Portfolio" prompt chain, which generates portfolio, strategy, condition and indicator JSON in nested prompts
Step 1
Test 1: iteratively create a simple RSI-based portfolio in Aurora, answering follow-up questions such as the initial value.
Step 2
Test 2: request the AAPL rate-of-change-of-SMA buy rule with a stop-loss strategy and a take-profit strategy.
Step 3
Inspect each generated portfolio JSON and record the approximate time of the final response.
How to read the measurements
Grading and valid output
Author inspection of the generated JSON. In Test 2, GPT-4o's buy strategy included conditions that were not specified and its stop loss was described as odd, while Claude's configuration was described as exactly what was articulated.
Cost
List prices shown in the article: GPT-4o $5.00/M input and $15.00/M output tokens. Claude 3.5 Sonnet $3/MTok input and $15/MTok output. No per-run spend is published.
Time
Approximate time to the final response: GPT-4o about 53.5 seconds (Test 1) and 44 seconds (Test 2). Claude 3.5 Sonnet about 83.5 seconds (Test 1) and around 180 seconds (Test 2). Intermediate responses took about 3 to 3.5 seconds for GPT-4o and 3.6 to 4 seconds for Claude.
Why this model was selected
The article judged Claude 3.5 Sonnet slightly better overall, citing more human-like responses and accurate complex portfolio configurations, while noting GPT-4o was faster.
See the published results
This image was published with the 2024-06-25 article. Read the source for the full test procedure and every result it reports.
Sample and scope
June 2024 comparison on two prompts with one run each. Both models have since been replaced.
Correctness is the author's own inspection of the JSON, and the article states the methodology is biased toward his use case. The article grades GPT-4o's Test 1 output as correct but does not state a correctness grade for Claude's Test 1 output, which it preferred for its human-like wording.
Times are approximate single observations of a multi-prompt chain, and prices are list prices at the time (GPT-4o $5.00/$15.00 per million tokens), not measured spend.
No comments yet.