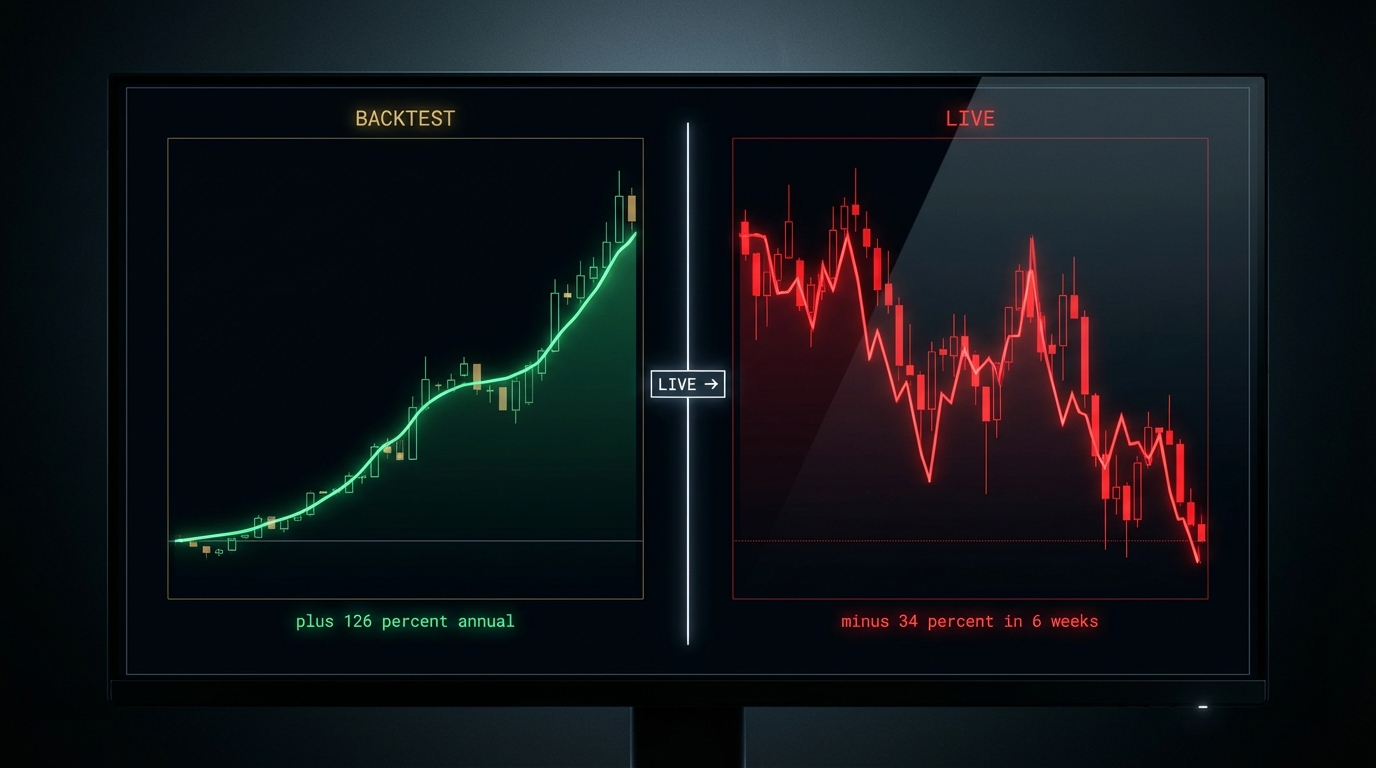
Imagine an agent trained toward one impressive backtest number, then failing after deployment. The opening +140% backtest and −30% live graphic illustrates that failure mode. The recorded experiment in this article is different: five hill-climbing cycles costing $676, with a first score of 71 and a final score of 27. It shows how evaluator feedback can steer the next search in the wrong direction.
Illustrative scenario: a $25,000 account loses 30% in five days. The curves below explain the failure mode; they are not recorded backtest or live results.
A gap between a backtest and later trading is a reason to investigate selection, execution assumptions, data availability and changing market conditions. Overfitting is one possible cause. A trace helps identify what the agent actually selected and which evidence it used; the gap alone does not settle the diagnosis.
Evaluation is the part of agent development that nobody talks about because most people building AI demos have never run a system long enough to see it fail. This article covers the engineering that keeps it from happening: traces, LLM judges, and a feedback loop that makes agents actually improve over time.
Module 5, Lesson 1: Evaluation and Traces. How do you know your agent is doing what you actually want?
The Problem
The optimization trap: when the agent succeeds at the wrong thing.
Every machine learning practitioner knows about overfitting. You train a model on historical data. It learns the data perfectly, including all the noise and anomalies that are specific to that dataset. When you expose it to new data, it falls apart because what it learned wasn't a real pattern.
AI agents have the same problem, and it's harder to catch. When you tell an agent to "build a trading strategy with the highest possible backtest return," it will do exactly that. It will explore every combination of indicators, time windows, and position sizes until it finds something that maximizes the metric you asked for.
The result looks impressive. 126% return in 2024. You show it to your friends. You write about it on Twitter. You deploy it with $25,000 on Monday.
By Friday you've lost 30%. The 2022 bear market destroyed it completely — either because the agent never tested 2022, or because the evaluation criteria didn't penalize drawdown, so the agent ignored it.
The optimization trap is an evaluation failure, not a model failure. The model did what you asked. You asked for the wrong thing.
The fix is not a better model. It's a better evaluator: one that grades the agent on what actually matters, penalizes single-year outlier returns, requires multi-regime evidence, and gets stricter every round.
I know this because I ran the experiment. Five rounds of hill climbing on a live trading agent. $676 spent. The first round scored 71 and produced an Iron Condor with a 54% average annual return. By Round 5, the score had dropped to 27 and the agent was recommending long directional options with a -6.3% average and a 92% drawdown in 2022. The evaluator caused every step of the decline. The full story is in the war story section below. Everything between here and there — traces, LLM judges, the feedback loop — is the anatomy of how it happened and how to stop it.
Observability
The flight recorder: what a trace actually is.
When a traditional app crashes, you read the stack trace. When an agent fails on iteration 7 of a 12-step ReAct loop (Reasoning + Acting: think, call a tool, observe the result, repeat), you're guessing — unless you have a trace.
A trace is a structured log of every step in the agent's execution. Think of it as a flight recorder. Every input the model saw, every decision it made, every tool it called, every result it got back, every token it spent, every millisecond it waited. If something goes wrong at 3 AM, you can reconstruct exactly what happened.
The shortened trace below illustrates the fields to capture: thought, tool input, tool output, cost and final answer. Its abbreviated identifiers and condensed tool payloads are explanatory examples. The recorded five-round experiment is linked in the war-story section; use the original run record for exact requests, outputs and deployment state.
Each iteration is a complete record: what the model thought, what it called, what came back, and what it cost. 12 iterations, $0.31 total. The trace is what makes debugging possible.
Without traces, a failed agent run is a black box. You see the final answer (or the error), and you guess at what went wrong. With traces, you can pinpoint the exact iteration where the model made a bad assumption, called the wrong tool, or misread a result.
Evaluation
How to grade an agent: algorithmic metrics and LLM judges.
Not all evaluation is the same. Some things you can measure with code. Some things you need a second AI to grade.
| Type | What it measures | Examples |
|---|---|---|
| Algorithmic | Objective, countable things. No model needed. | Total cost, iteration count, latency, Sharpe ratio, max drawdown, whether a strategy was deployed |
| LLM Judge | Subjective quality that requires reasoning. | Did it explain the strategy logic clearly? Did it test enough different structures? Is the recommendation realistic for a real account? |
Use deterministic calculations for measured return, drawdown, costs and order validity. Use an LLM judge for process questions: did the agent identify missing evidence, follow the frozen plan and explain the observed result? Neither a confident judgment nor tests over several already-seen regimes establish how the rule performs on independent later data.
Here's the actual system prompt for the NexusTrade Agent Run Evaluator:
The caps constrain a grading policy; they do not remove selection bias. There is also an unresolved inconsistency in the reproduced record: 54.34% average return falls in the printed 30–59% band, whose fitness cap is 6, but the Round 1 output below reports fitness 7. Its dimension scores of 7, 7, 6 and 5, combined with the printed 40%, 25%, 20% and 15% weights, yield 65/100 rather than the reported overall 71. Keep the historical output intact and recover its exact prompt/scoring revision before treating the cap table as a validated implementation.
A corrected procedure separates three checks. First, code checks the stated account limits and the actual orders: for example, a 59% drawdown fails a chosen 50% ceiling. Second, the judge reviews whether the research followed its plan without inventing evidence. Third, freeze the complete rule and evaluate it on a chronologically later period withheld from both search and grading. A failed gate stays visible even when the model calls the result promising.
The shortened trace calls 59% drawdown acceptable despite a stated 50% threshold. That is the conflict to catch in this example. If the account’s rule is a 50% ceiling, the candidate fails it; changing the ceiling is a new documented decision, not an exception silently granted by a judge.
Here's what the evaluator looks like in the course exercises, running against a real Aurora agent run:
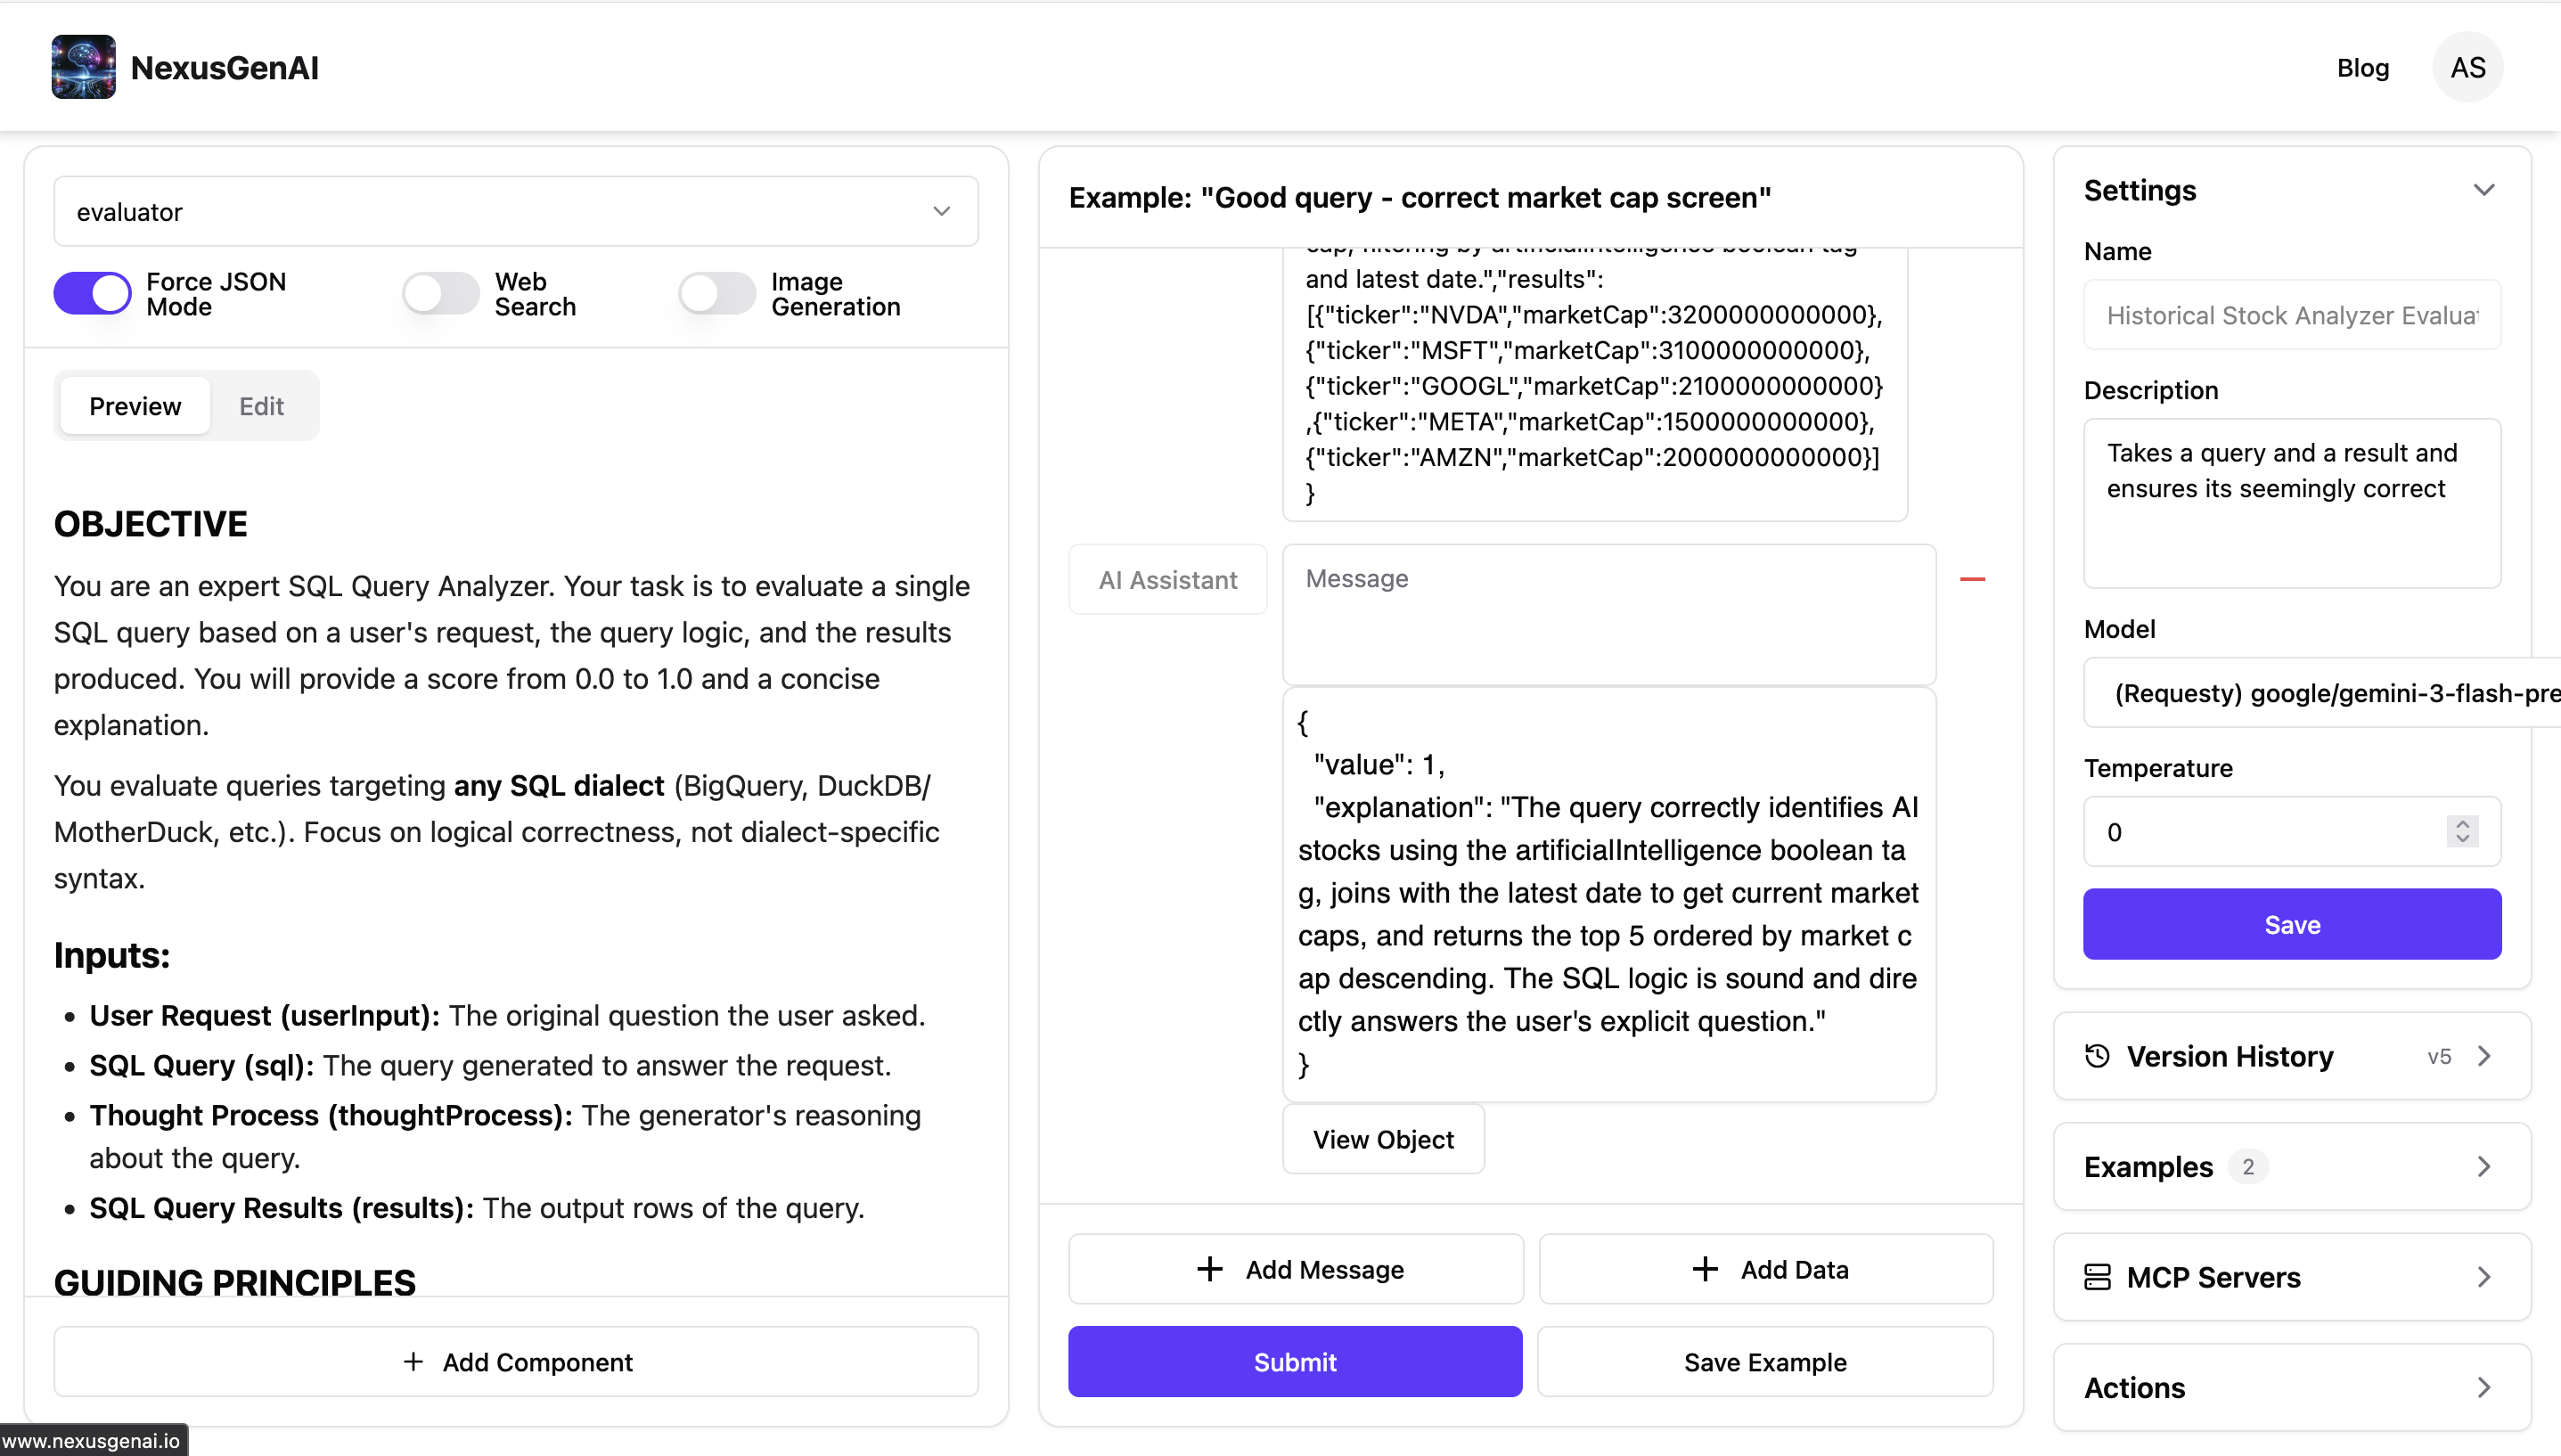
The evaluator reads the full agent trace and returns structured JSON: dimension scores, an overall grade, a deployment verdict, and a nextIteration note that seeds the next run.
And it returns structured JSON. Here's what Round 1 of the hill climbing experiment produced:
The nextIteration field is what makes the loop work. It becomes the seed for the next agent run: here's what you did well, here's what was wrong, here's what to focus on. The evaluator writes the coach's notes.
You call it from anywhere via MCP:
Going Deeper
Beyond hill climbing: four approaches to agent optimization.
Once you have traces and an evaluator, the natural next step is to close the loop: run the agent, score the output, use that score to improve the next run. The simplest version of this is hill climbing — run, grade, seed the next run with the feedback. Cheap, fast, and often enough for early iteration.
But hill climbing is a local search. It follows the gradient of whatever metric you give it. Point it at the wrong objective and it will confidently optimize you into a cliff. The research community has gone considerably further. Here's the landscape:
The common thread: all four require traces, all four require a scoring function, and all four fail if that scoring function points at the wrong objective. But they're not interchangeable. Here's why you don't just default to NSGA-II:
For most teams: start with hill climbing. Run it until it stalls. If you hit a genuine multi-objective tradeoff, consider NSGA-II — but only with automated infrastructure and a clear budget. The rubric is still load-bearing in all four cases. Here's what it looks like when the rubric fails.
Real-World Evidence
I ran this loop five times. The first round was still the best.
Production Architecture
The feedback loop: how evaluation connects to memory.
Evaluation doesn't mean much if the agent can't learn from it. The feedback loop is what turns a one-time grade into compounding improvement.
The full pipeline has five steps. Each one feeds the next:
The agent receives its task, reads injected memory from past runs, and works through the ReAct loop. Every decision, every tool call, every result is captured.
agent.run({
  task: "Build options strategy",
  context: injected_memory,
  maxIterations: 20
})
→ agent_id: "69d49c..."
→ status: "completed"
→ iterations: 12
Run → Trace → Judge → Memory → Improve → repeat. Each loop produces a labeled training example: what the agent did, how it scored, and what to do differently next time.
Keep the time boundary visible: search and grading → freeze the rule and evaluation plan → inspect one reserved later result → monitor subsequent decisions. If the agent reads that later result and revises the rule, the period has become selection data. Mark it consumed in memory and reserve a new later test; do not relabel the revised result as independent. A useful regression case is a judge that says “increase return” after a risk-limit failure: the next run must retain the failed gate and consumed-period label rather than dropping them from context.
What makes Step 5 concrete: the injected memory isn't an abstract "past context" flag. It's a literal block of text prepended to the next agent's system prompt — the AgentSummary record retrieved from MongoDB and formatted as natural language instructions. Here's what that block looks like at the start of Round 2:
The evaluator doesn't just grade — it writes the next run's starting conditions. That's the loop. And as the war story above shows, get the rubric wrong and the injected note corrupts every run that follows. A demo runs once. A system runs, gets graded, and improves — or degrades, depending on what you told it to optimize for.
Connect
Expose your agent to the world: the NexusTrade MCP server.
Everything in this article — traces, LLM judges, feedback loops — is built on Aurora's infrastructure. The same evaluator that graded the hill climbing experiment. The same backtester the agent used to test the Iron Condor across 2021-2024. Those tools are accessible via MCP, which means you can call them from Claude Desktop or Cursor without touching the NexusTrade UI.
The MCP server exposes the full tool surface: screener, portfolio system, backtester, indicator engine, and the evaluator itself. Here's the config:
Then from Claude Desktop or Cursor, you can ask: "Use NexusTrade to screen for stocks with RSI below 40 trading above their 200-day moving average." Claude calls screen_stocks on the NexusTrade MCP server. The server returns live results from the same screener Aurora uses internally. No copy-paste. No API docs. One tool implementation, available from any MCP-compatible client.
You can also run the evaluator directly. run_agent_run_evaluator(agent_id) grades any completed agent run from any client. The evaluation loop becomes accessible from wherever you're working.
Click to sign in and install the MCP server in one step.
Check Your Understanding
Pop quiz.
What is a trace in the context of AI agents?
An agent produces a 126% backtest return in 2024, but you only have one year of data. The evaluator gives it a high score. What's wrong?
When would you use an LLM judge instead of an algorithmic evaluator?
True or false: the evaluation feedback loop requires both evaluation AND memory to work. Having only one of the two is not enough.
The End
You've built the complete agent. This is where most people stop. It's where you start.
Five articles. Five modules. You started with a leaked source file and ended with a production evaluation loop — router, ReAct engine, long-term memory, rubric design, feedback loop. The only thing left is to run it.
The $676 hill climbing experiment is a better argument for evaluation than anything else in this article. The agent wasn't broken. The rubric was. Build the right rubric and the loop compounds toward something real. Build the wrong one and a perfectly obedient agent will follow it off a cliff, five rounds in a row, at $135 per run.
Before the capstone, here's the full series in five minutes. Every concept, every module, from the leaked source file to the production feedback loop.
The full course recap. Five modules in five minutes. Watch this before running the capstone.
The capstone lives inside the free course, not in this blog series. The full pipeline is embedded directly in the lesson, no separate window, no instructions to follow in another tab. Aurora runs inline: screens the market, validates with news, builds a watchlist, then wires up a scheduled agent to manage it every week.
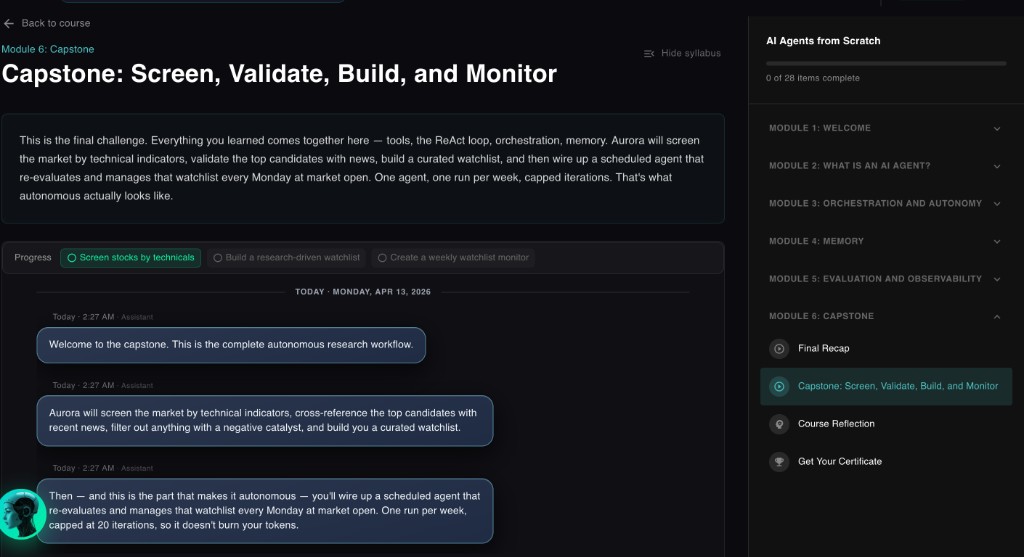
The capstone runs Aurora directly in the lesson page. Three steps: technical screen, watchlist, weekly monitor agent. The progress bar tracks where the agent is. You watch every tool call happen in real time.
Free. No credit card. The capstone lesson in the course runs Aurora inline: screen, validate, build a watchlist, wire up a weekly monitor. Takes about 20 minutes.
Run the Capstone Free → Or open Aurora directly →
No comments yet.