TL;DR
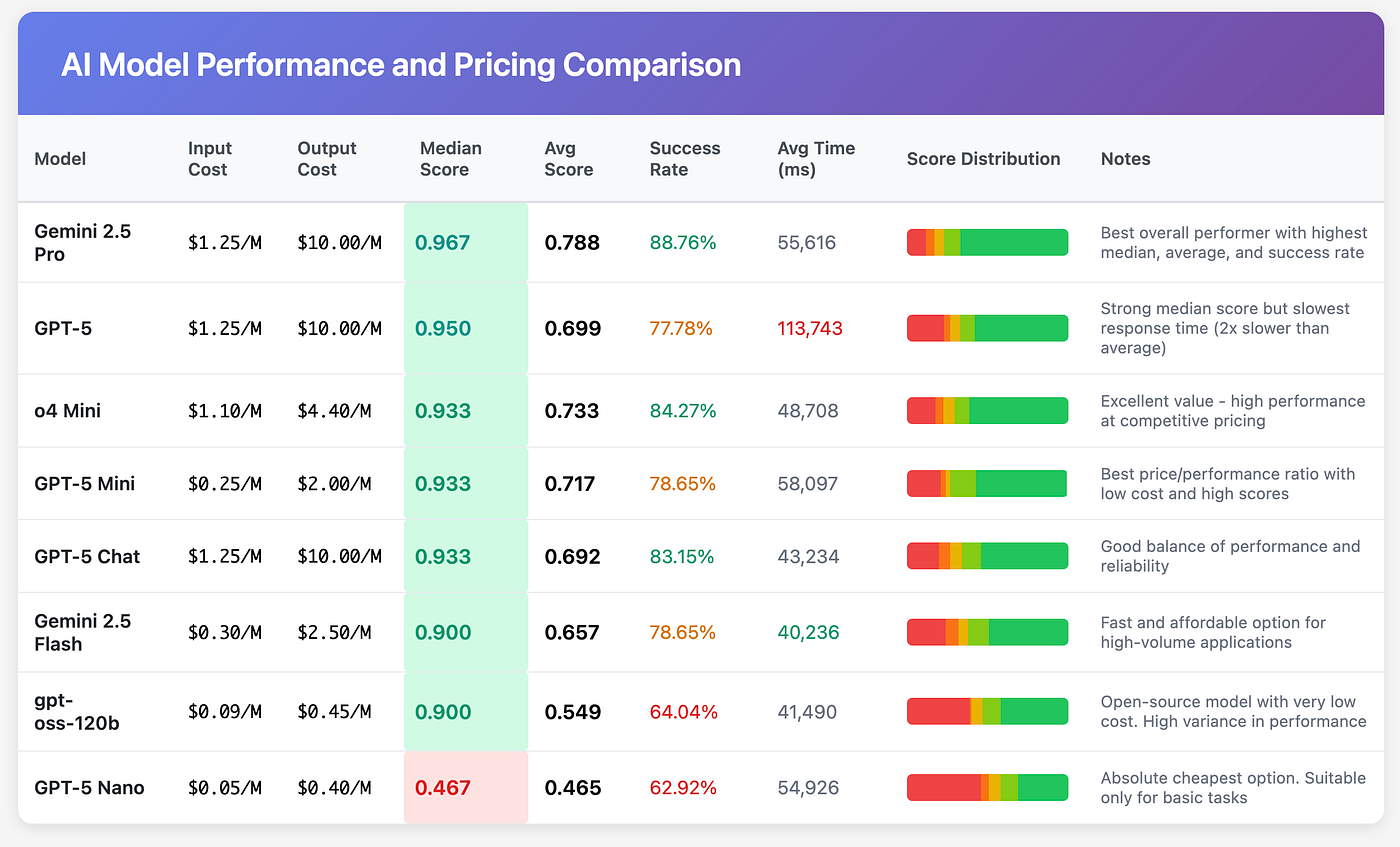
Published 2025-08-10. Gemini 2.5 Pro has the highest published median (0.967), average score (0.788) and success rate (88.76%). GPT-5 scores a 0.950 median and 0.699 average with the slowest average time (113,743 ms), while GPT-5 Mini scores 0.933 and 0.717 at $0.25/M input.
- Published
- 2025-08-10
- Published model rows
- 8
- Evidence
- Historical task evaluation
Follow this evaluation
Published results
GPT-5 family and peers generating financial SQL queries: source evidence dated 2025-08-10.
- Exact model version
- Gemini 2.5 Pro
- Median score
- 0.967
- Avg score
- 0.788
- Success rate
- 88.76%
- Avg time
- 55,616 ms
- Input cost
- $1.25/M
- Output cost
- $10.00/M
The displayed values belong to the identified model versions and this published task, with their original metric units.
What did this task require the model to return?
Read the tested version, task and rubric together. Check failures alongside successful answers; compare costs only within the reported unit.
2025-08-10: GPT-5 family and peers generating financial SQL queriesKeep the study date and exact model ID beside the result. Do not average different tasks into one winner.
Test a strategy with Aurora
Keep the study date and exact model ID beside the result. Do not average different tasks into one winner.
Test a strategy with AuroraKeep reporting dates and units beside the answer, and inspect its original citations.
Published results
EvaluateGPT financial question set (count not restated in this article), 8 models. Published 2025-08-10. Values retain their original units and grading scale.
See the complete published results
Scroll sideways to compare all columns. Select a heading to sort.
| Gemini 2.5 Pro | 0.967 | 0.788 | 88.76% | 55,616 ms | $1.25/M | $10.00/M |
| GPT-5 | 0.950 | 0.699 | 77.78% | 113,743 ms | $1.25/M | $10.00/M |
| o4 Mini | 0.933 | 0.733 | 84.27% | 48,708 ms | $1.10/M | $4.40/M |
| GPT-5 Mini | 0.933 | 0.717 | 78.65% | 58,097 ms | $0.25/M | $2.00/M |
| GPT-5 Chat | 0.933 | 0.692 | 83.15% | 43,234 ms | $1.25/M | $10.00/M |
| Gemini 2.5 Flash | 0.900 | 0.657 | 78.65% | 40,236 ms | $0.30/M | $2.50/M |
| gpt-oss-120b | 0.900 | 0.549 | 64.04% | 41,490 ms | $0.09/M | $0.45/M |
| GPT-5 Nano | 0.467 | 0.465 | 62.92% | 54,926 ms | $0.05/M | $0.40/M |
No matching rows. Clear the filter to see all records.
EvaluateGPT financial question set (count not restated in this article), 8 models. Published 2025-08-10. Values retain their original units and grading scale.
Task and tested input
Generate syntactically and semantically valid SQL queries for real-world financial questions.
Instruction in brief (task summary)
Each model generates a SQL query for each financial question in the EvaluateGPT set. The article does not publish the questions and refers to the GPT-oss article for the procedure.
How the runs worked
EvaluateGPT financial question set (count not restated in this article), 8 models
EvaluateGPT: generated SQL executed against a financial database, then scored 0 to 1 by LLM judges
Step 1
Run the EvaluateGPT financial question set on eight models.
Step 2
Execute each generated SQL query against the database.
Step 3
Score each query and its results 0 to 1 with LLM judges and report median, average, success rate and time per model.
How to read the measurements
Grading and valid output
LLM-judge scores from 0 to 1 as described in the linked GPT-oss article (Claude Sonnet 4, Gemini 2.5 Pro and GPT-4.1 judges in that article). This article does not restate the judges.
Cost
List prices per million tokens, from $0.05/M input and $0.40/M output (GPT-5 Nano) to $1.25/M input and $10.00/M output (Gemini 2.5 Pro, GPT-5, GPT-5 Chat). Total spend was reported as around $200.
Time
Average time in milliseconds, from 40,236 ms (Gemini 2.5 Flash) to 113,743 ms (GPT-5).
Why this model was selected
The article said it would not use GPT-5 for this task and would use o4-mini, and called GPT-5-mini the standout budget model, matching o4-mini at a quarter of the cost.
See the published results
This image was published with the 2025-08-10 article. Read the source for the full test procedure and every result it reports.
Sample and scope
This is a single launch-week run (August 2025) with the GPT-5 versions and prices of that week. The article itself calls its verdict a task-specific launch-week judgment.
The article's own text says an earlier paragraph conflicted with the table and that cost and speed ratios need the original run table. Only the published table values are used here.
GPT-5's success rate (77.78%) is a whole-number fraction of 90, while every other row is a whole-number fraction of 89, so GPT-5 may have been scored on a different question count. Judges include models from the tested families.
No comments yet.