TL;DR
Published 2025-02-05. Gemini 2.0 Flash scored 1/1 on both questions at $0.10 input and $0.40 output per million tokens. o3-mini scored 0.7/1 and 1/1, and DeepSeek R1 scored 0.7/1 and 0/1.
- Published
- 2025-02-05
- Published model rows
- 3
- Evidence
- Historical task evaluation
Follow this evaluation
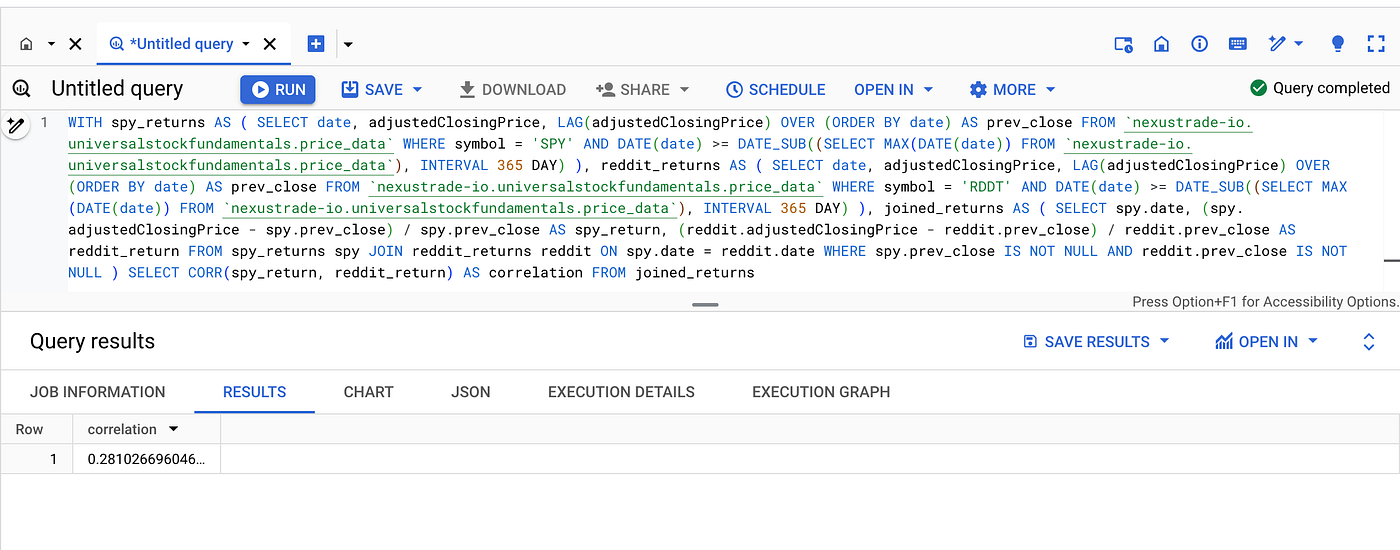
Published results
Gemini 2.0 Flash, DeepSeek R1 and o3-mini writing financial SQL: source evidence dated 2025-02-05.
- Exact model version
- Gemini Flash 2.0
- Q1: RDDT vs SPY return correlation
- 1/1
- Q2: biotech revenue growth
- 1/1
- Input price (per 1M tokens)
- $0.10
- Output price (per 1M tokens)
- $0.40
The displayed values belong to the identified model versions and this published task, with their original metric units.
What did this task require the model to return?
Read the tested version, task and rubric together. Check failures alongside successful answers; compare costs only within the reported unit.
2025-02-05: Gemini 2.0 Flash, DeepSeek R1 and o3-mini writing financial SQLKeep the study date and exact model ID beside the result. Do not average different tasks into one winner.
Test a strategy with Aurora
Keep the study date and exact model ID beside the result. Do not average different tasks into one winner.
Test a strategy with AuroraKeep reporting dates and units beside the answer, and inspect its original citations.
Published results
2 natural-language financial questions, 3 models, one attempt each. Published 2025-02-05. Values retain their original units and grading scale.
See the complete published results
Scroll sideways to compare all columns. Select a heading to sort.
| Gemini Flash 2.0 | 1/1 | 1/1 | $0.10 | $0.40 |
| OpenAI o3-mini | 0.7/1 | 1/1 | $1.1 | $4.4 |
| DeepSeek R1 | 0.7/1 | 0/1 | $0.75 | $2.4 |
No matching rows. Clear the filter to see all records.
2 natural-language financial questions, 3 models, one attempt each. Published 2025-02-05. Values retain their original units and grading scale.
Task and tested input
Generate a BigQuery SQL query that answers a natural-language financial question over the NexusTrade stock dataset.
Published prompt excerpt
What is the correlation of returns for the past year between reddit stock and SPY? / What biotech stocks have increased their revenue every quarter for the past 4 quarters?
How the runs worked
2 natural-language financial questions, 3 models, one attempt each
NexusTrade natural-language stock query prompt, with generated SQL executed in BigQuery against the NexusTrade fundamentals dataset
Step 1
Send each of the two questions to Gemini Flash 2.0, DeepSeek R1 and OpenAI o3-mini.
Step 2
Execute each generated query in BigQuery and inspect the result. Fix typos manually where needed to see whether the logic was right.
Step 3
Score 1 for a correct first attempt, 0.7 for a correct query that needed a manual fix, 0 for an invalid query. For question 2, ask o3-mini-high to grade the returned query.
How to read the measurements
Grading and valid output
Author-assigned per-question scores. On question 1, R1 misspelled adjustedClosingPrice and o3-mini used the ticker REDDIT, so both received 0.7 after a manual fix. On question 2, R1's query failed to execute (0/1), and o3-mini-high graded both the Gemini and o3-mini queries 9/10, which the author recorded as full credit.
Cost
OpenRouter list prices per million tokens as shown in the article: Gemini Flash 2.0 $0.1 input and $0.4 output. DeepSeek R1 $0.75 input and $2.4 output. O3-mini $1.1 input and $4.4 output. No per-run cost is published.
Time
The article publishes no per-model timing. It describes Gemini as responding in a couple of seconds, R1 as taking more than 30 seconds on question 1, and o3-mini as taking a few seconds.
Why this model was selected
The article selected Gemini 2.0 Flash, removed DeepSeek R1 from NexusTrade and added Gemini to the AI chat as the "Balanced Performance & Value" model, citing its accuracy, price, speed and context window.
See the published results
This image was published with the 2025-02-05 article. Read the source for the full test procedure and every result it reports.
Sample and scope
This February 2025 comparison covers two questions with a single attempt per model, so one typo moves a model's score substantially.
Scores were assigned by the author, with a partial 0.7 for queries that needed a manual fix. There is no blind or automated grader for the first question.
These model versions and list prices have since been replaced, and the article reports speed only in qualitative terms.
No comments yet.